Arrhythmia Analysis Accelerator : A-Cube
We propose the A-Cube design methodology to create medical decision support on the edge. The design and implementation of an atrial fibrillation detector hardware core was selected as a proof-of-concept study. To facilitate the required atrial fibrillation functionality, we adopted an established AI model, based on Long Short-Term Memory (LSTM) technology for hardware implementation. The adaptation was done by varying design parameters such as data window and the number of LSTM units. We found that a data window of 40 beats and 20 LSTM units are sufficient to achieve a classification accuracy of 99.02%. We are confident that the A-Cube methodology can be used to implement this model in hardware. Doing so, will create a low power and low latency atrial fibrillation monitoring solution which has the potential to extend the observation duration while being convenient for patients.
Physical Implementation
Technology selection
Some investigation was made between the trade-offs between using TSMC 65nm and 28nm technology nodes. To begin with a synthesis run for 65nm was completed and found the accelerator to be significantly larger than expected.
After this some tests were done using TSMC 28nm to compare the area, power, and cost of the dies. Showing that the reduction in core area leads to a more reasonable cost of the die, whilst also giving better power performance.
| TSMC 65nm LP | TSMC 28nm HPC+ | |
|---|---|---|
| Die Size | 2.2 x 2 mm | 1.5 x 1 mm |
| SRAM Memory | 64 KiB | 64 KiB |
| Accelerator Area (µm2) | 2,440,320 | 726,110 |
| Gate Count | 445,197 | 575,824 |
| Accelerator Power (mW) | 722 | 201 |
| Clock Speed (MHz) | 240 | 240 |
| Projected Cost | 13,541 | 10,777 |
Timing closure
Whilst investigating the use of TSMC 28nm libraries, this did introduce some violations in the timing closure. After a long time of investigating different possible causes, we finally figured out that the issue was the choice in standard cell libraries.
At 65nm, there were 3 track height options and 3 threshold voltage options. But for 28nm there were 3 track heights, 4 threshold voltages and 3 channel length options. Without really understanding the differences, we decided to use the 12-track S-VT and largest channel length. This would normally provide a fairly high performance design, as the drive strength of the cells would be quite high.
The problem however was in the balancing of setup timing and hold timing. The violations we had were in the hold timing, which requires longer delay paths to accomodate for. The EDA tools weren't able to insert enough delay for the hold timing to overcome the massive drive strength of the cells.
After some investigation we found that the 7-track S-VT library gave a good balance between the hold and setup timing. This also was the main reason for the large power reduction, as the drive strength of the cells is much lower.
Floorplanning
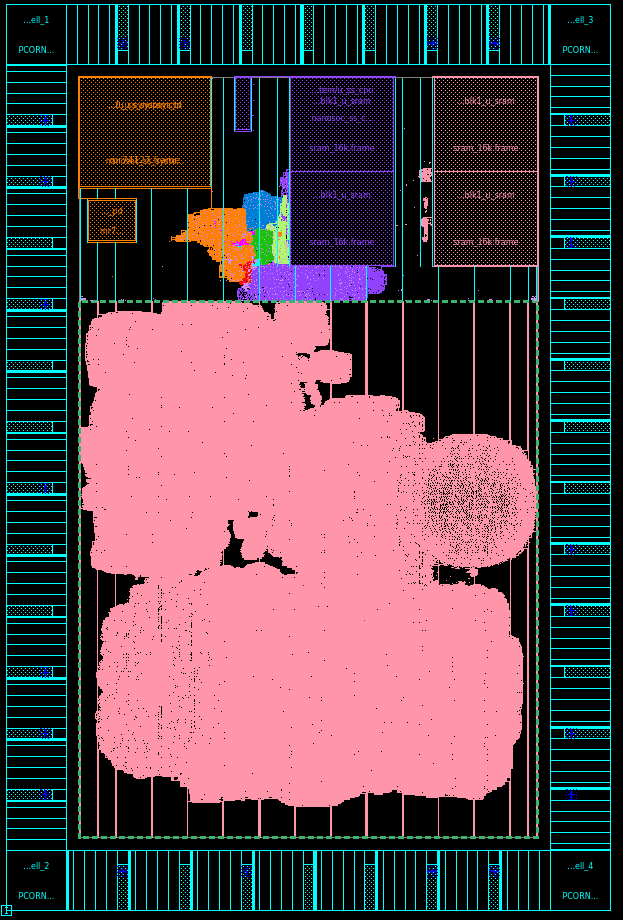
The floorplan for the die is shown as below. The bottom area (pink) is the A Cube design, with the top area being the core SoC of nanoSoC. There is currently quite a significant amount of 'spare' area. Partly this is whilst we are still developing the flow, and if we need to decrease cell density due to routing congestion (which is much more significant in the 7-track library), but also partly due to restriction in the cell height in mini ASICs. The height has to be a multiple of 0.5mm, and it was found that 1mm was too small, so 1.5mm was chosen.
Physical Verification
After spending a lot of time trying to figure out why timing wasn't working, and finally figuring it out, we'd hoped that then the implmentation would be 'nice and easy'. However, when trying to verify the gate level simulations, we ran into some issues. Initially, we found that the accelerator would output x's after being loaded with values and trying to run the calculations.
We managed to get past this issue by moving the HLS backend from using Vivado/Vitis, to using Siemens Catapult. This also seemed to give a much cleaner RTL for ASIC implementation. However this still gave x's from the output of the accelerator.
So we then tried running the synthesis directly in Catapult, and importing the netlist into the design. This way Catapult would hopefully setup all the constraints etc. correctly for the implementation of the accelerator. However, this gave new issues, it seemed after running gate level simulations that the data does not get properly captured by the accelerator from the system, so the accelerator then stalls.
It seems to be that either
- The synthesis process is breaking the accelerator somehow
- The boundary between nanoSoC and the accelerator is not working properly after synthesis
Currently we are trying to run different permutations in the Catapult synthesis, then in the full system design to get a clean result in the backend. But unfortunately the run time for Catapult is about 6-7 hours, and then synthesis of the full system is another 5-6 hours, and gate level simulations take a few hours to run and debug. This results in quite a lengthy debug cycle between stages.
Project Milestones
Do you want to view information on how to complete the work stage ""
or update the work stage for this project?
-
Getting Started
Design FlowTarget DateCompleted DateImplement and test the Soclab encryption example in the ZCU104 FPGA board.
-
Behavioural Modelling
Design FlowTarget DateCompleted DateImplement an atrial fibrillation detection model in the ZCU104 FPGA board.
-
data model
Design FlowTarget DateAnalyse the model performance based on different signal length and algorithm complexity.
-
data model
Design FlowTarget DateAnalyse the model performance based on different quantisation levels.
-
Behavioural Design
Design FlowTarget DateSelect a suitable implementation candidate to server as atrial fibrillation detection core.
-
Behavioural Modelling
Design FlowTarget DateCompleted DateSimulate (RTL) the selected atrial fibrillation detection core.
-
Generate RTL
Design FlowTarget DateImplement an AHB bus interface for the selected atrial fibrillation detection core.
-
Generate RTL
Design FlowTarget DateIntegrate Nanosoc and the selected atrial fibrillation detection core.
-
Simulation
Design FlowTarget DateCompleted DateSimulate the integration results.
-
RTL Verification
Design FlowTarget DateCompleted DateImplement the integration results in the ZCU104 FPGA board.
-
RTL Verification
Design FlowTarget DateTest the hardware on the ZCU104 FPGA board.
-
Technology Selection
Design FlowTarget DateCompleted DateExplore technology nodes for implementation
Result of WorkSynthesis comparison between TSMC 65nm and 28nm found that the cost/area would make more sense to run on 28nm as the core area was too large
-
Timing closure
Design FlowTarget DateCompleted DateResult of WorkNo timing violations in design
Team
 Project Creator
 rami hariri
researcher student
at anglia ruskin university
Research area: AI
Submitted on
Comments
Abstract
We propose the A-Cube design methodology to create medical decision support on the edge. The design and implementation of an atrial fibrillation detector hardware core was selected as a proof-of-concept study. To facilitate the required atrial fibrillation functionality, we adopted an established AI model, based on Long Short-Term Memory (LSTM) technology for hardware implementation. The adaptation was done by varying design parameters such as data window and the number of LSTM units. We found that a data window of 40 beats and 20 LSTM units are sufficient to achieve a classification accuracy of 99.02%. We are confident that the A-Cube methodology can be used to implement this model in hardware. Doing so, will create a low power and low latency atrial fibrillation monitoring solution which has the potential to extend the observation duration while being convenient for patients.
Add new comment
To post a comment on this article, please log in to your account. New users can create an account.